Structured Logging Standards for Production Applications
Enforcing a shared data contract prevents queryable logs from becoming expensive unstructured data.
Structured logging is not a syntax question. The production failure that matters is not skipping JSON. It is adopting JSON without a data contract, so three services write three different field names for the same concept and no query can reconstruct what happened. This article walks through the contract itself: the base fields, the severity rules, the trace context, the redaction paths, and the pipeline gate that enforces it all.
Why treating structured logging as a formatting choice leads to queryability problems at scale
A payment service logs userId. An auth service logs user_id. A notification service logs uid. All three refer to the same customer, but each has named the field differently. You cannot pull the full timeline for one user across those three services with a single query, because the query must account for every variant the same way unstructured logs require regex parsing. The format is machine-readable. The meaning is scattered.
The practical consequence is the same operational cost as plain text. Dashboards and alerts must carry a mapping of every variant, and a new variant introduced in a deployment silently breaks the existing queries. Structured logging only delivers its value when "structured" means a shared data contract. Stable field names, typed values, agreed severity semantics, mandatory context fields, and PII discipline are enforced properties, not aspirations. A JSON log stream without those properties is unstructured data wearing structured clothing.
The minimum viable log schema: which fields are non-negotiable and why each one earns its place
Every log line from every service must carry a small set of base fields. Each one answers a question that cannot be reconstructed after the fact if it was never recorded, so each earns its place by making retrieval possible. The base set is timestamp, level, service, event, and trace identifier.
The service field identifies the originating service. It must be stable and consistent, not the container hostname or a generated pod name, because cross-service queries filter on this field to narrow results to the component that emitted the line. When a deployment regenerates pod names, filtering on that value becomes a moving target and the field stops narrowing anything.
The event field is the primary grouping key for dashboards and aggregations. It should be a snake-case, past-tense verb phrase such as order_placed, payment_failed, or user_authenticated, not a free-text sentence. The contrast is concrete. logger.info("Batch processed 1000 records in 2.3 seconds") is a sentence for humans. event: batch_processed, records: 1000, duration_ms: 2300 is data for machines and humans, where every field is filterable, aggregatable, and dashboard-ready.
Deployment metadata is injected via environment variables or a sidecar, not hard-coded into the application. Domain-specific fields like user_id, order_id, and tenant_id are added alongside the base fields. The base field names never change across services, and the contract is additive, not restrictive. If a field means the same thing across services, it must have the same name.
How severity levels function as a cost and signal control, and why INFO is the most abused level in production
Severity levels are a routing and cost primitive, not a developer preference. Misusing INFO as a catch-all level inflates log volume, buries genuine signals, and drives up ingestion costs. Under-used WARN and ERROR make alerting unreliable: you can no longer tell what needs attention from what is normal.
The production definitions are specific. ERROR means something failed and requires attention: a database query threw an exception, a payment was declined unexpectedly. Alerting systems should watch this level. WARN means something unexpected happened but the system recovered: a retry succeeded on the second attempt, a cache miss triggered a fallback, a deprecated endpoint received traffic. INFO means normal business events that matter for operations: a user signed up, an order shipped, a deployment completed. The test is whether the event would be meaningful to an operator reviewing the log an hour later. DEBUG captures internal state for development or active troubleshooting, and it should be off in production by default.
The most common mistake is logging too much at INFO. If a message fires thousands of times per minute during normal operation, it belongs at DEBUG or should not exist. High-frequency INFO logs are the primary driver of observability cost inflation, and the volume asymmetry is large. DEBUG-level emission can generate orders of magnitude more log volume than INFO-level, which translates directly to ingestion and storage cost. The signal consequence is equally severe. When every log line carries ERROR, nothing is. Severity levels only function as a routing signal when the semantics are enforced consistently across every service, which requires a shared definition rather than individual developer judgment.
Trace context propagation: how a single shared identifier reconstructs a distributed request timeline
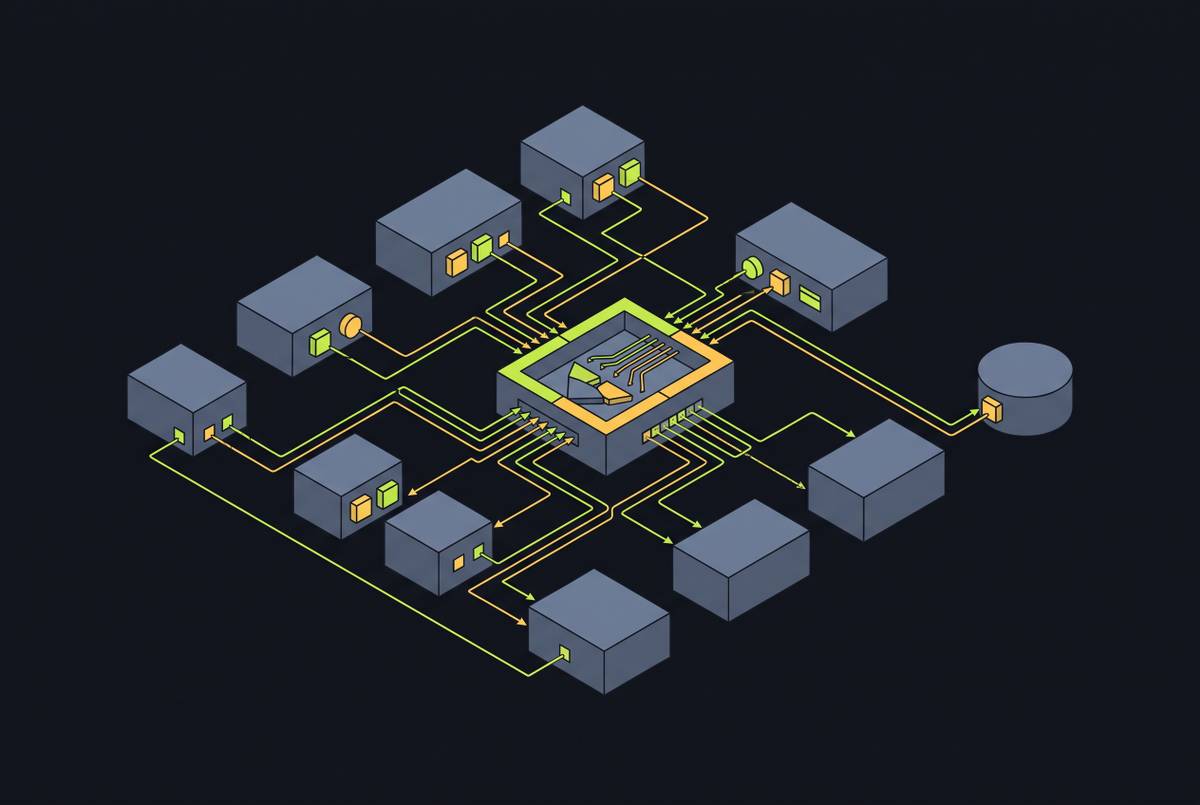
A trace ID propagated across every service boundary is the single highest-leverage addition to any log schema. It converts a distributed set of isolated log lines into a reconstructable request timeline without requiring a dedicated tracing backend to be queried first. The mechanism is simple. A correlation ID, also called a request ID or trace ID, is assigned at the entry point of every request by the API gateway, the load balancer, or the first service to receive it. It is propagated through every downstream service call via HTTP headers or message queue metadata. Every log line emitted during that request, across every service, carries the same identifier.
The debugging consequence is immediate. A single user-facing action, clicking "Buy Now", triggers requests across a chain of services from API gateway to auth to inventory to payment to notification. Without a shared identifier, these logs are isolated islands. The trace ID is the thread that stitches them together. OpenTelemetry defines a 128-bit trace identifier shared across every service involved in processing a single user-facing request. Attaching it to log lines allows finding all logs produced by a single request, and the span_id narrows the search to a specific operation within that request.
Attach it once to the logger's context, at the request boundary, rather than passing it manually to every log call. In asynchronous Python services, contextvars propagates request-scoped state correctly across await boundaries without leaking between concurrent requests. Some teams rely on timestamps for correlation. That fails under load. Parallel requests overlap in time, and clock skew between services introduces ambiguity that a shared identifier eliminates even when NTP is running.
PII redaction as a schema decision, not a developer responsibility
PII leakage into logs is an architectural failure, not a human error. The only reliable defense is a logging configuration that makes it structurally impossible to serialize sensitive fields, not a code-review convention that relies on developers remembering to strip them. Structured logging makes PII exposure easier, not harder, when the library is misconfigured. A JSON serializer will dump an entire request object, including authorization headers, session tokens, and personal data, unless explicit redaction paths are configured.
The fix is at the library level. In Pino, the redact configuration prevents PII leakage during serialization, making it impossible for a developer to accidentally log a credit card number even when they pass the full payment object. The censor value [REDACTED] appears in the log, so field presence is preserved for schema validation without exposing the value. Fields that must never appear in logs include passwords, tokens, API keys, session cookies, social security numbers, credit card numbers, authorization headers, and personal identifiers.
The compliance consequence is direct. In regulated environments, every log line containing a patient identifier or account number becomes subject to HIPAA or PCI-DSS retention and access control requirements. The simplest compliance path is not logging that data at all, because a log that never contained PII requires no special handling. For HIPAA specifically, every audit record must include a timestamp, the accessor identity, the action performed, and a reference to the PHI accessed. What is required is a structured record of access, not the PHI itself. Systems that generate these records automatically in structured JSON are deployable. Systems requiring manual log correlation create compliance gaps.
What compliance frameworks actually require from log data and why a well-designed schema satisfies them by default
A structured log schema with stable fields, correct timestamps, trace context, redacted PII, and mandatory service metadata satisfies the evidence requirements of SOC 2 Type II and HIPAA without additional post-processing. The fields auditors need are either present in every log line, or absent by design. SOC 2 Type II covers a six-to-twelve month period of continuous evidence of control operation. Audit logs must be generated continuously from the first day of deployment. Systems where logging was added after the fact are significantly harder to audit, because the evidence window is shorter and the schema may be inconsistent across the period.
Log integrity is a SOC 2 control in its own right. Logs must be trustworthy, and the evidence chain includes clock synchronization via NTP, write-once storage, log hashing, encryption in transit with TLS 1.2 or higher, encryption at rest with AES-256, and restricted write and delete permissions. AWS S3 Object Lock in Compliance mode prevents deletion before the retention period expires even by a root user. Retention requirements differ by framework and determine the cold-tier configuration, not just the hot-tier incident response window. PCI DSS mandates 12 months of log retention. HIPAA applies a 6-year retention standard. The direction of compliance in 2026 is toward ongoing risk evaluation rather than annual checklists. Auditors expect evidence that risk assessments are revisited regularly.
Log volume as a cost problem that schema discipline directly solves
Uncontrolled log volume is a material cost center, and the most effective cost controls only work when every log line has stable, typed fields that automated routing rules can act on without pattern matching. Tiered retention routing, severity-based filtering, and sampling of high-frequency paths all rely on fields being present and consistent. With structured fields, routing rules execute reliably at ingest time. Unstructured logs require regex matching that breaks when a developer changes a message string.
For high-frequency counting events such as health check successes or routine cache hits, converting from logs to metrics is the most cost-efficient reduction path. Metrics are orders of magnitude cheaper than equivalent log volume. This decision belongs in the schema design phase, not after cost bills arrive. Grafana Loki's storage model illustrates the principle. Loki stores only log labels in its index rather than full text content, which significantly reduces storage costs compared to fully indexed alternatives, and it integrates with Prometheus and Grafana dashboards. The label set is, in effect, the structured schema applied at the storage layer.
Pipeline validation: enforcing the schema contract at ingest rather than discovering drift during an incident
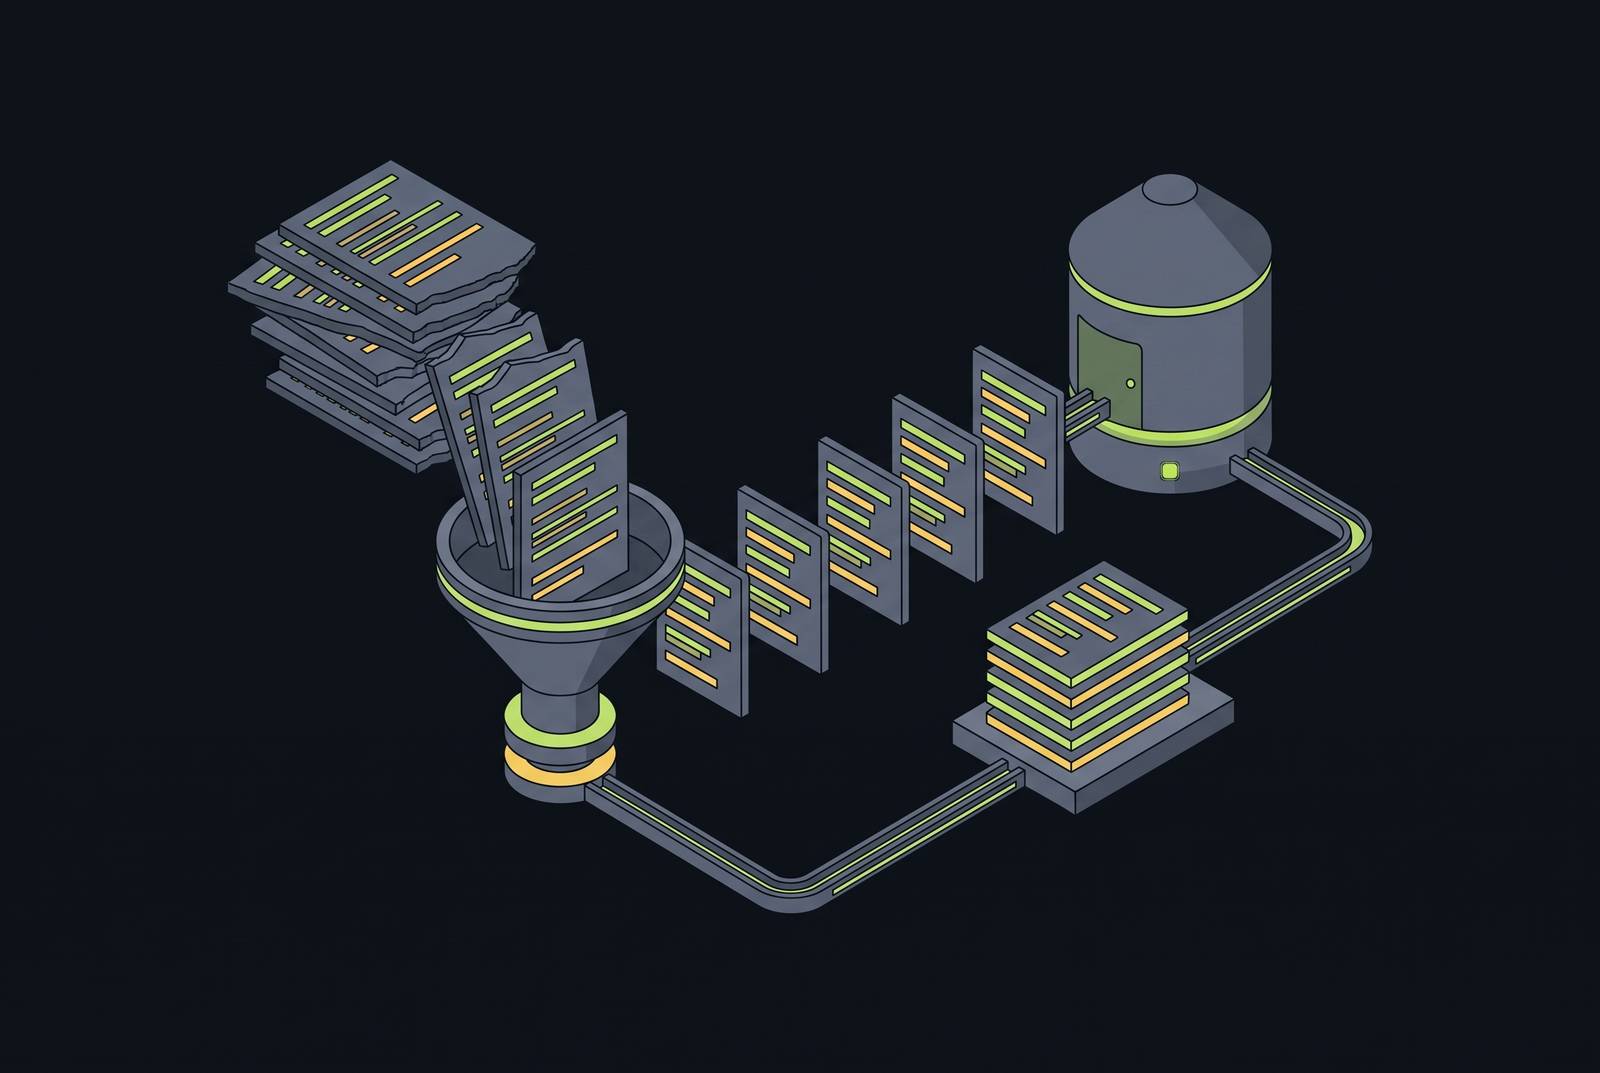
Schema drift happens continuously during normal development cycles. A new service ships with a different field naming convention. A library upgrade changes the serialization format. A developer adds a log call that includes a raw object instead of selected fields. None of these are caught by code review at scale. The only durable enforcement point is a validation gate in the collection pipeline, which catches malformed or non-compliant log lines before they reach indexed storage, where they become invisible until an incident makes their absence obvious.
Pipeline-level enforcement has concrete mechanisms. Fluent Bit with Lua filters or Vector's remap transforms can reject log lines that fail schema validation, and with reroute_dropped enabled, failed events can be quarantined to a separate pipeline before they reach storage tiers. A validation gate in the CI/CD pipeline tests that a service's log output matches the shared schema before a deployment is promoted, catching field-name changes at the source rather than downstream. Never assume applications will continue emitting valid JSON after a deployment. Validate continuously, not just at initial integration.
OpenTelemetry provides a vendor-neutral enforcement layer by defining common instrumentation and transport for metrics, logs, and traces. Teams can swap or combine observability backends without rewriting application instrumentation, and teams on multiple clouds get a single, governed pipeline with one place to redact sensitive content, enrich spans with environment metadata, and route signals before anything leaves the network. Container runtimes handle stdout capture, and additional wrapping breaks pipeline parsing. Shared logging libraries are the organizational enforcement mechanism. Provide a configured logging library that emits compliant output by default, with base fields, redaction paths, and the event naming convention baked in. Individual services add domain-specific fields without touching the base configuration.
The development-environment exception and the human-readability trade-off
The human-readability objection to structured logging is real but scoped to development environments only. The correct answer is environment-aware configuration, not abandoning JSON in production or compromising the schema to accommodate local developer experience. Structured logging reduces human-readability, which matters when a developer is debugging locally. Configuring the logging framework to output a semi-structured, colorized format in development while defaulting to JSON in production resolves this without changing application code. Only the formatter changes.
The storage overhead of JSON versus plain text is also real. Repeated field names increase message size. The mitigations are at the pipeline layer: field-name shortening in the schema design phase, compression at ingest, and selective field inclusion based on environment and log level. Teams that use logs heavily for alerting versus teams that reserve logs for investigation and use metrics for alerting represent a genuine architectural split. The answer is not to pick a side. The schema enables both, because structured fields support metric-style aggregation queries and forensic investigation. The data contract is the work. JSON is just the transport.